Blake Schmitt · 25 October 2026
Tracking Performance Metrics in Custom-Built Visibility Platforms During Service Provider Switches
Custom-built visibility platforms help organizations monitor search rankings, site exposure, and related digital signals across multiple channels, and these systems require careful performance oversight especially when companies decide to switch underlying service providers. Data shows that seamless transitions depend on continuous collection of metrics such as query response times, data freshness intervals, and ranking accuracy percentages because any gap in monitoring can lead to incomplete visibility reports for weeks afterward.
Core Components of Visibility Platforms
Visibility platforms typically aggregate data from search engines, social signals, and content indexes through APIs and crawlers, while custom builds allow teams to tailor data pipelines to specific business needs like regional keyword sets or industry-specific ranking factors. Observers note that organizations often maintain these platforms internally to avoid vendor lock-in, yet the architecture still relies on external providers for raw data feeds and hosting resources. Research indicates that custom configurations frequently incorporate modular data layers, which makes it easier to swap providers without rebuilding entire data ingestion processes from scratch.
Key architecture elements include real-time dashboards, historical data archives, and alert systems that flag sudden drops in coverage or accuracy, and these components must remain operational throughout any provider changeover. Studies from academic institutions reveal that platforms built with containerized services experience fewer disruptions because individual modules can be redeployed on new infrastructure while preserving metric collection continuity.
Primary Metrics for Ongoing Oversight
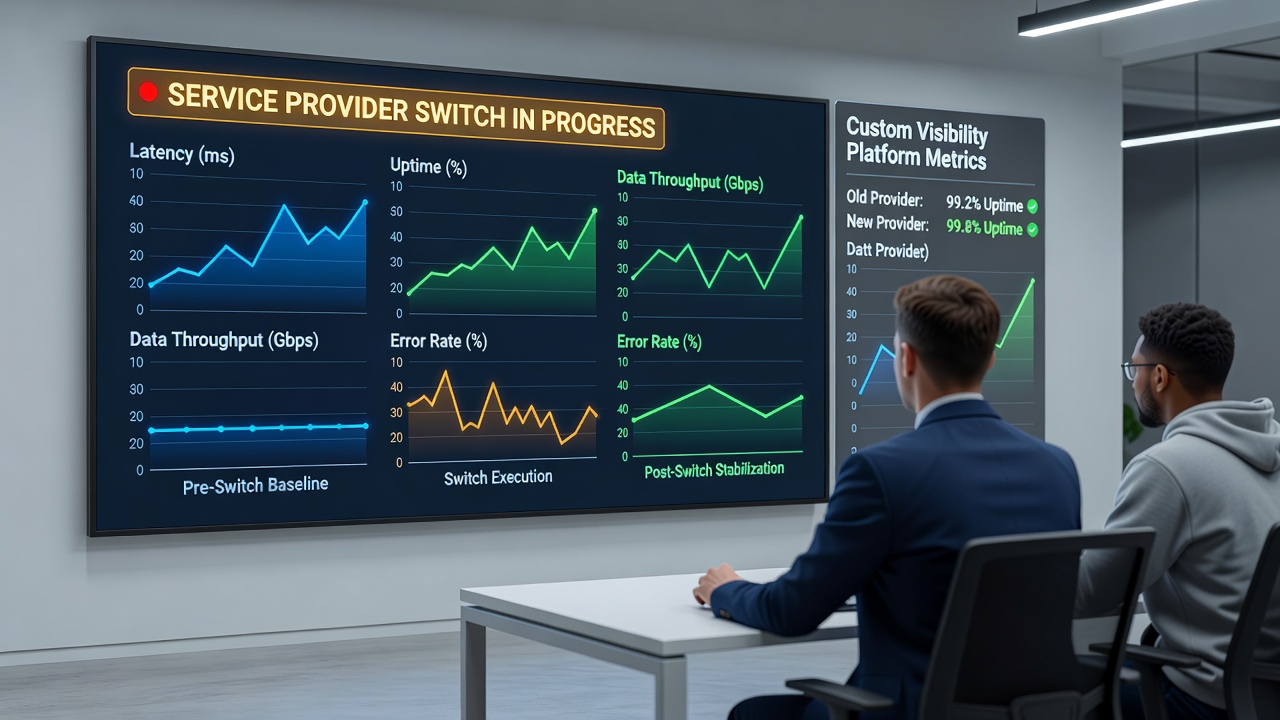
Performance tracking centers on several measurable indicators that reveal system health during transitions. Uptime percentages, measured at five-minute intervals, provide immediate signals of service availability, whereas latency figures for API calls indicate whether new providers deliver comparable speed. Data accuracy rates, calculated by cross-referencing sampled rankings against manual verification, help confirm that the switch has not introduced systematic errors in visibility scores.
Additional metrics encompass crawl completeness ratios, storage utilization during data archiving, and error rates for failed queries, and together these figures create a comprehensive view of platform stability. Figures from industry reports demonstrate that teams tracking at least eight distinct metrics achieve higher success rates in maintaining reporting consistency across provider changes.
Challenges Encountered in Provider Transitions
Switching service providers introduces risks such as temporary data gaps, authentication mismatches, and shifts in data formatting standards that can break existing metric pipelines. Those who have managed these projects report that API version differences often surface only after cutover, forcing rapid adjustments to parsing scripts. In October 2026, several organizations noted increased complexity when new data sovereignty requirements altered how certain providers handled regional information flows, requiring metric dashboards to incorporate additional compliance checks.
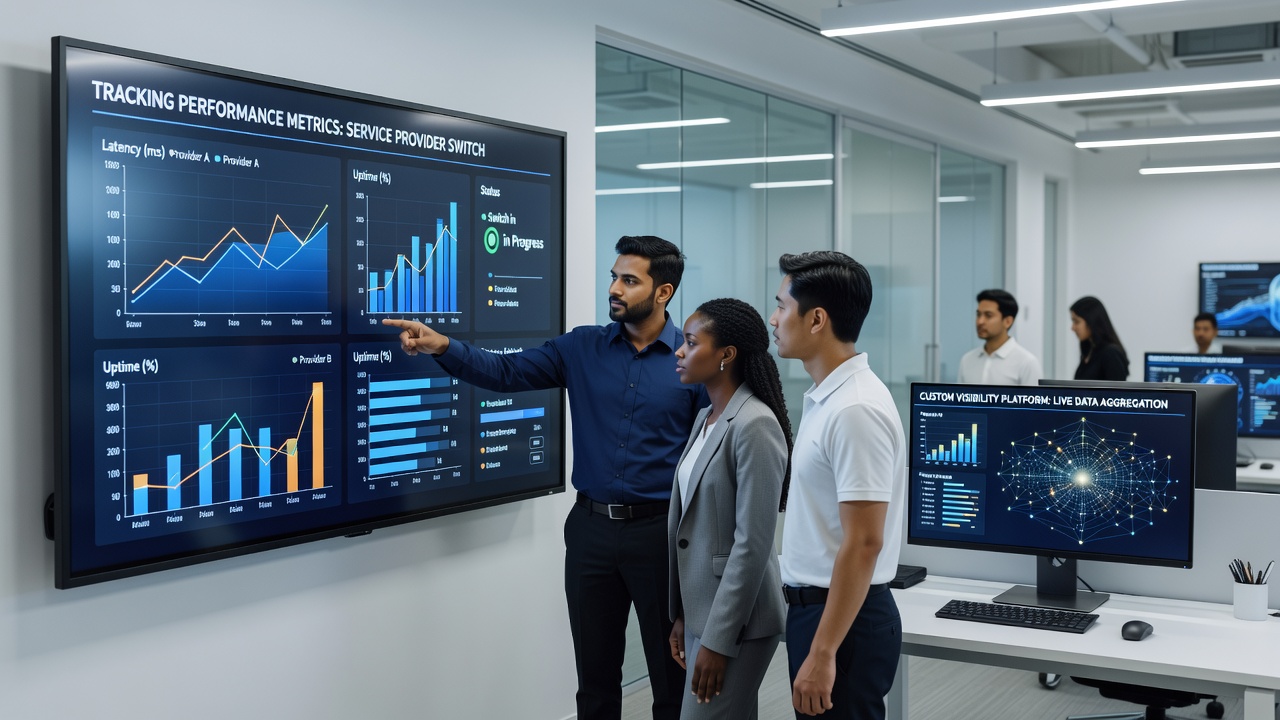
Bandwidth spikes during bulk data migrations can also skew performance readings if not isolated from normal operational metrics, and observers have documented cases where unfiltered migration traffic masked underlying latency issues. Effective tracking therefore involves establishing baseline values for each metric at least thirty days before the planned switch so deviations become immediately visible.
Methods and Tools Supporting Metric Continuity
Teams maintain continuity by deploying parallel monitoring instances that run alongside legacy and new provider environments for a defined overlap period, allowing direct comparison of outputs. Automated scripts capture and store metric snapshots at regular intervals, while visualization layers highlight trends across the transition window. According to guidance from the National Institute of Standards and Technology, structured logging combined with threshold-based alerts reduces the time needed to identify and resolve post-switch anomalies.
Integration with third-party benchmarking services further strengthens oversight because these services supply independent reference points for ranking data, and such cross-verification helps isolate provider-specific variances. Research published by European academic consortia shows that organizations using standardized metric schemas across environments experience twenty percent fewer reconciliation issues after cutover.
Conclusion
Tracking performance metrics throughout service provider switches requires deliberate planning around data collection points, baseline establishment, and continuous comparison mechanisms because these steps preserve the reliability of visibility insights. Organizations that implement layered monitoring approaches consistently report smoother transitions with minimal impact on downstream reporting accuracy. As platforms evolve and new regulatory considerations emerge, the discipline of rigorous metric oversight remains central to maintaining operational integrity in custom-built systems.